robots.txt audit and fix, checked in Search Console
robots.txt can block important pages and resources by accident, or leave cart pages, internal search and tracking parameters open for Google to waste time on. I go through the file line by line, fix the wrong rules, and check the result in Search Console's robots.txt report. ₪290 one-time.
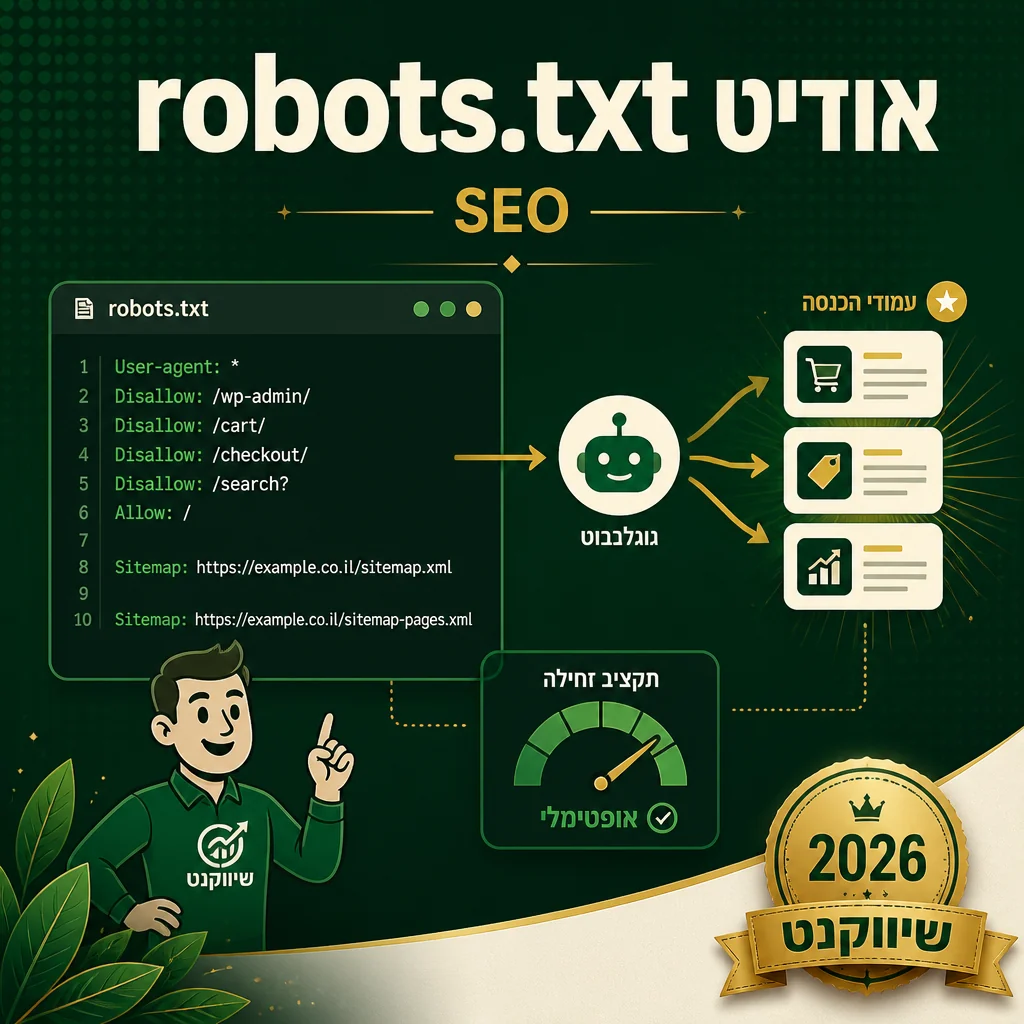
Why a clean robots.txt matters
- ✓ A wrong block on folders like /wp-content/ or /assets/ stops Google from loading your CSS and JS, so it cannot see the page the way visitors do
- ✓ Focused blocks on cart pages, internal search and tracking parameters leave Google more crawl time for your product and content pages
- ✓ A Sitemap line inside robots.txt helps Google and other search engines find the sitemap even without manual submission
- ✓ The robots.txt report in Search Console shows which file Google actually fetched, when, and whether it hit errors or warnings
robots.txt is a text file at the root of the site that tells search engine crawlers which URLs they may access. One overly broad Disallow line can block crawling of a whole section, so it is worth checking every time the site structure changes.
Important: robots.txt does not keep a page out of Google. Google states that a blocked URL can still be indexed if other pages link to it, just without a description. To keep a page out of the index you need a noindex rule or password protection, and in that case the page must not be blocked in robots.txt, or Google will never see the noindex.
The audit starts with the existing file compared against the Page indexing report in Search Console, then a check in the robots.txt report, which replaced the old robots.txt Tester in late 2023. I then write a corrected file, deploy it, request a recrawl of the file from the report, and confirm with URL Inspection that the important pages are open to crawling.
Find wrong blocks
Every Disallow line is compared against the Page indexing report, and important pages or resources blocked by accident get surfaced.
Point crawling at the right pages
Cart pages, internal search and tracking parameters that do not need crawling get blocked, so Google focuses on pages that bring you customers.
Blocking versus removal
Pages that need to leave the index get noindex, not Disallow, so they do not linger in results without a description.
robots.txt report check
After deployment I confirm in Search Console's robots.txt report that Google fetched the new file without errors, and check key pages with URL Inspection.
How we work
- 1
Scan the existing file
I pull the current robots.txt, review every line, and compare it against the Page indexing report to find wrong blocks.
- 2
Map pages that do not need crawling
I identify URLs like /cart/, internal search and UTM parameters, and separate what needs a crawl block from what needs noindex.
- 3
Write the corrected file
A new file with CSS and JS left open, a Sitemap line, and only focused blocks.
- 4
Deploy and verify
Push to production, request a recrawl of the file in the robots.txt report, confirm key pages are open, and deliver a change report.
robots.txt audit pricing
Includes the file scan, fixes, a Sitemap line, and verification in Search Console's robots.txt report.
Get a custom quoteOr see all SEO packages →
FAQ
Does robots.txt prevent indexing?
No. robots.txt blocks crawling, so Google does not read the content, but a blocked URL can still appear in results if links point to it, just without a description. To keep a page out of Google, use a noindex rule on the page or password protection. Note that if the page is blocked in robots.txt, Google cannot see the noindex.
What happened to the robots.txt Tester in Search Console?
Google retired it at the end of 2023 and replaced it with the robots.txt report, found under Settings in Search Console. The report shows which robots.txt files Google found for your site, when they were last crawled and any warnings or errors, and lets you request a recrawl of the file after an urgent fix.
Should I block UTM parameter URLs?
Usually not as the first fix. UTM parameters create duplicate URLs for the same page, but if those URLs are blocked in robots.txt, Google cannot read the canonical tag on them. The cleaner fix is a canonical tag on every page pointing to the clean version, and no UTM links in your internal linking. I add a robots.txt block for parameters only when they create crawling waste at scale.
Let us help
Send a message describing what you need and we will reply with a quote and recommended next step within an hour during business hours.
Related
- SEO service · Search Console Google Search Console monitoring — see what is working be...
- SEO service · Sitemap Sitemap.xml — dynamic, submitted, monitored monthly
- SEO service · Page indexing Page indexing report cleanup: every URL classified and re...
- SEO service · Indexing Indexing fix — root cause via URL Inspection, page by page
- SEO service · Removals Remove URLs and sensitive content from the Google index